Description
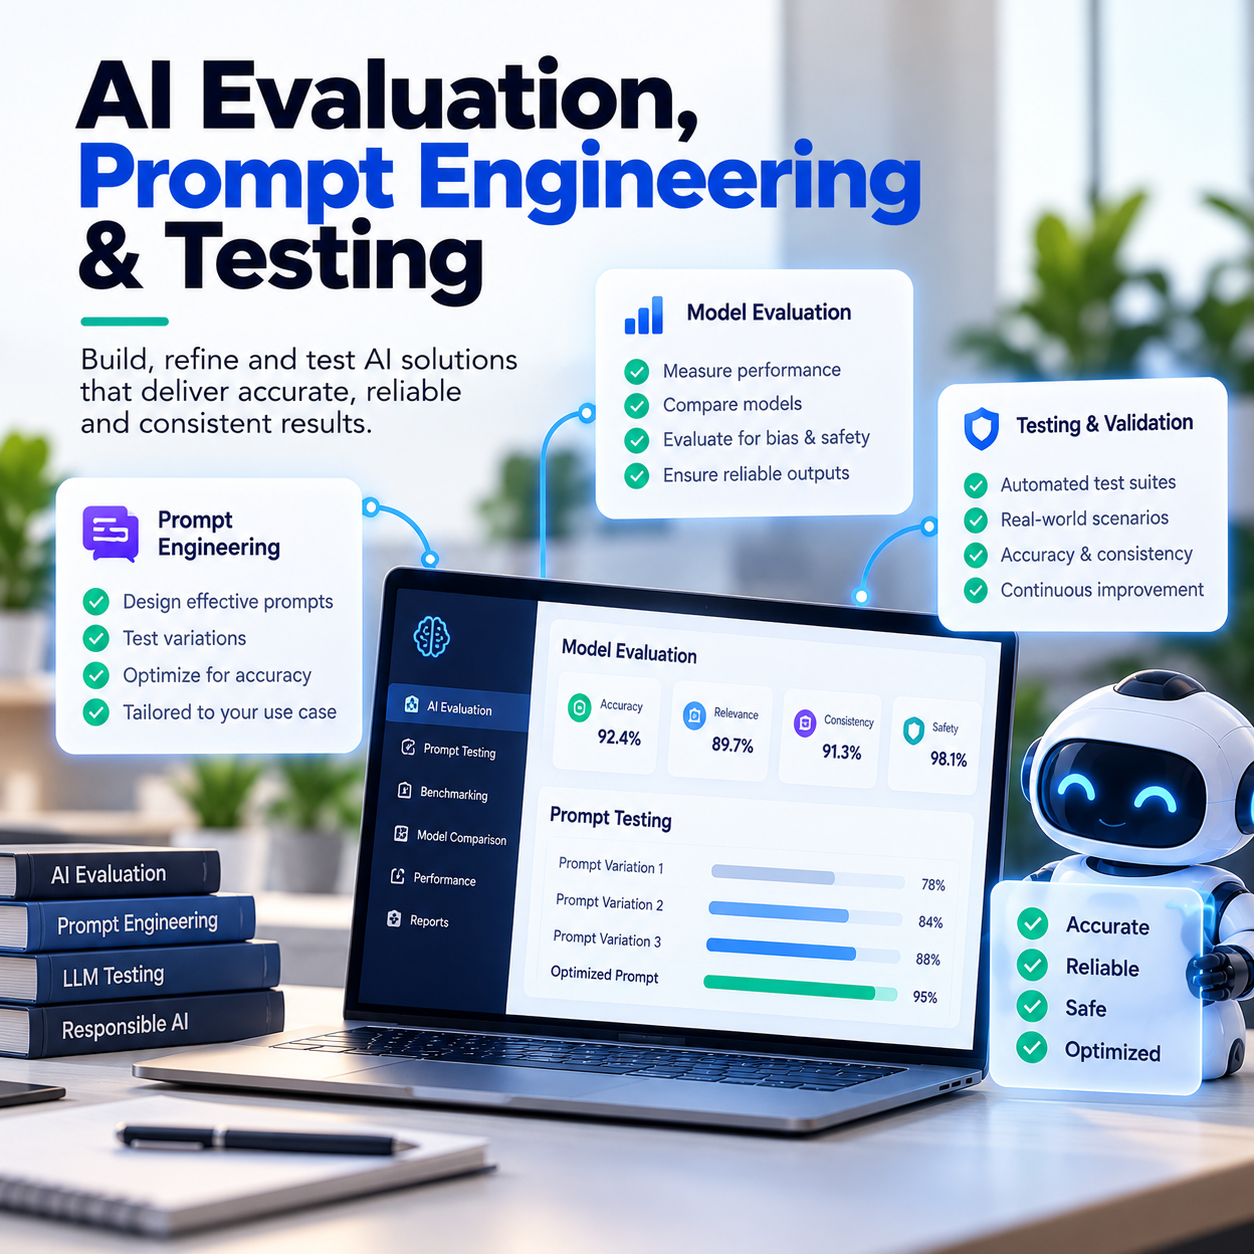
Replace guesswork with a repeatable way to test and improve prompts, AI agents, and generated outputs before they reach more users.
What this helps you achieve
- Define what a good AI response means for your use case
- Find weak prompts, inconsistent behaviour, and common failure modes
- Compare prompt or model changes against the same test set
- Improve consistency, usefulness, and safety of AI outputs
- Create a practical quality baseline for future iterations
What we deliver
- Use-case and success-criteria definition
- Prompt review and targeted prompt engineering
- Representative test-case and evaluation-set creation
- Quality, consistency, and failure analysis
- Scorecard, recommendations, and next-step testing plan
Choose the right package
| Package | Best for |
|---|---|
| Starter | One use case, prompt review, a focused test set, and practical improvement recommendations. |
| Standard | Multiple prompts or use cases, structured evaluation, regression testing, and a clear quality scorecard. |
| Premium | A broader evaluation framework with edge-case testing, prompt or model comparison, guardrail recommendations, and a production-readiness plan. |
How it works
- Understand the AI feature, target users, risks, and desired outcomes.
- Create representative examples and define evaluation criteria.
- Test the current behaviour, improve prompts, and compare the results.
- Deliver the findings, recommended changes, and a repeatable testing approach.
Who this is for
product teams, agencies, AI startups, and businesses that are building or deploying AI features and need more dependable outputs.
Important: Evaluation results are only as useful as the examples and success criteria supplied. Model usage, testing infrastructure, and API costs are separate.
Ready to get started? Choose the package that best matches your current scope. After checkout, we will confirm your goals, access requirements, preferred tools, and delivery plan before implementation begins.